Toward Active-Vision Foundation Models
Yohaï-Eliel Berreby
Sabrina Du
McGill University Mila – Quebec AI Institute

Deep neural networks as models of vision

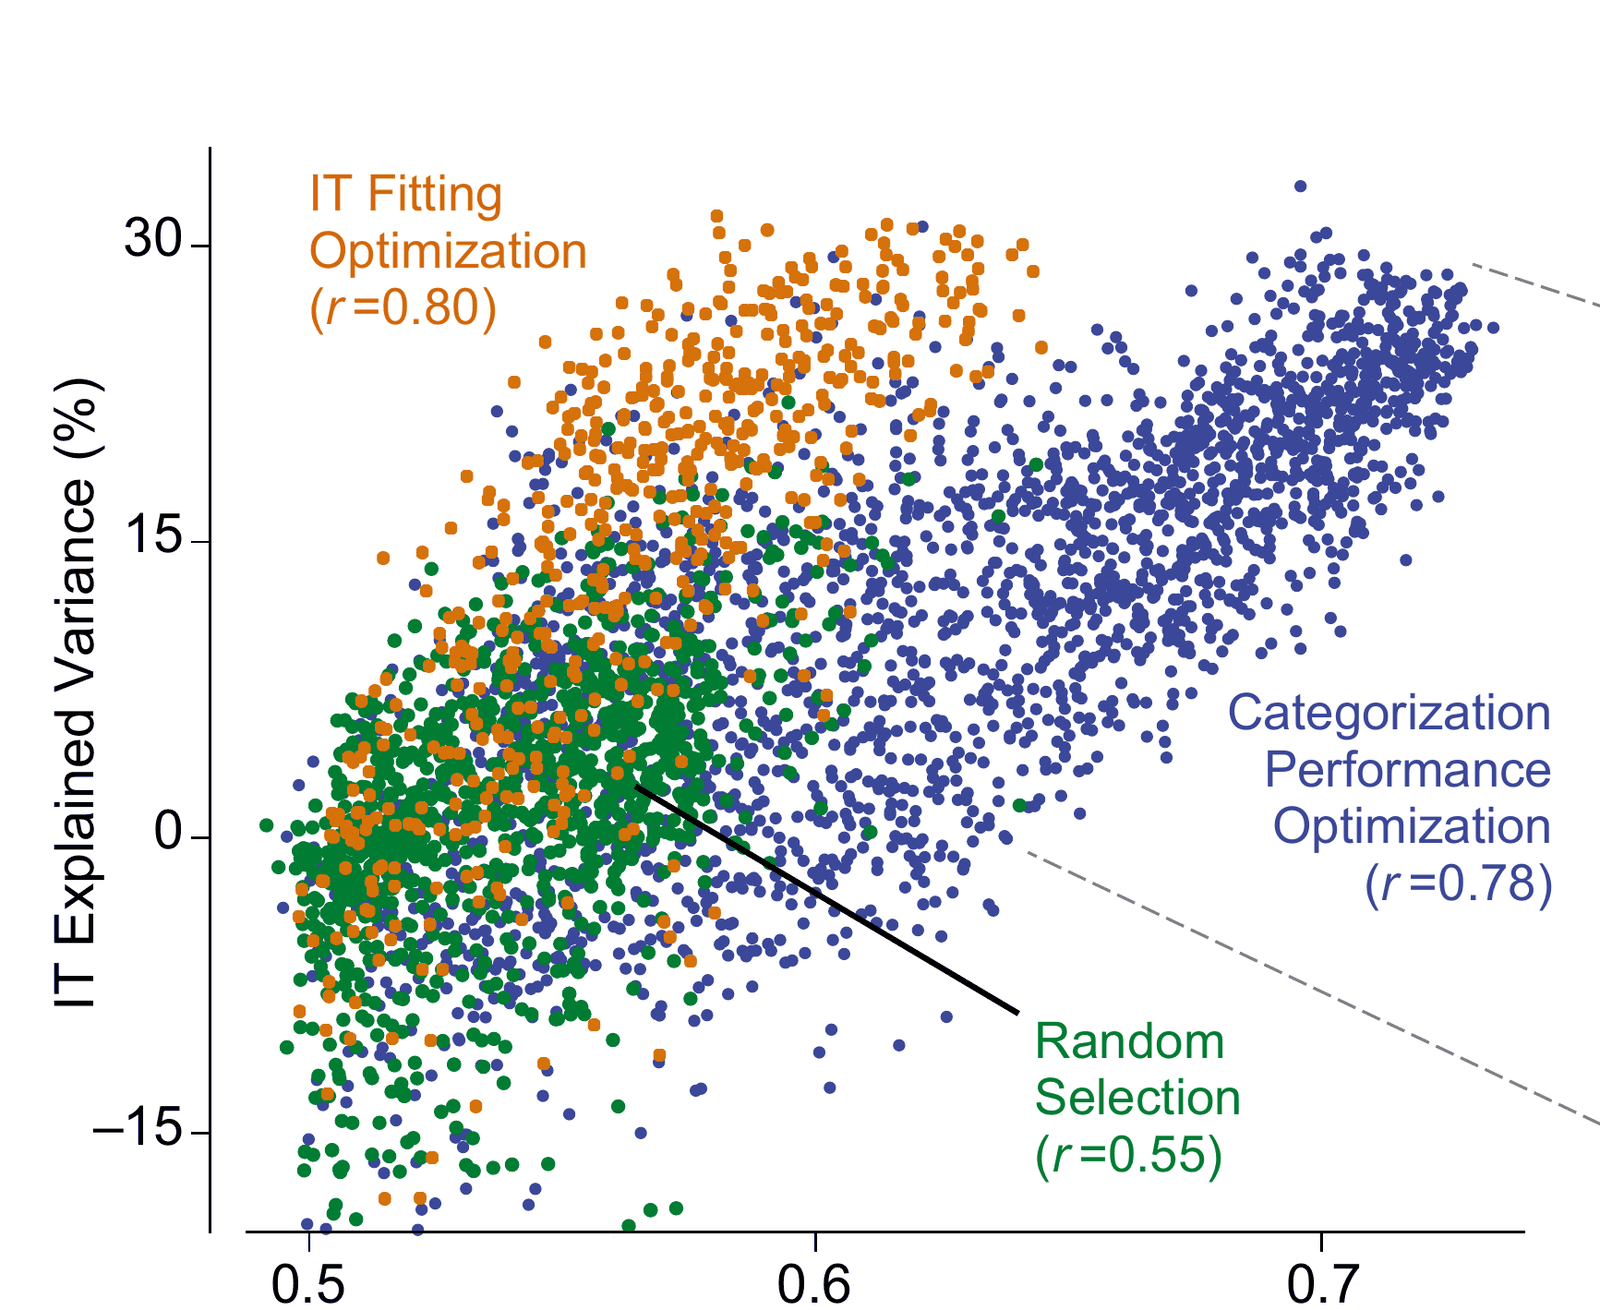
Categorization performance against IT neural predictivity for thousands of models

Categorization performance

SupervisedYamins et al. 2014, PNAS

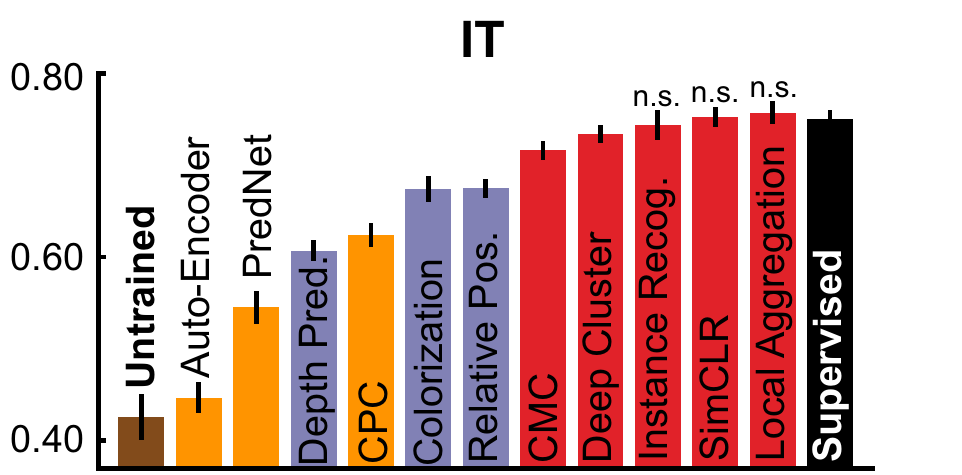
Noise-corrected IT predictivity

Noise-corrected IT predictivity of networks trained without labels against a supervised network: several contrastive models, among them SimCLR and Local Aggregation, are not significantly different from the supervised one
Unsupervised / self-supervisedZhuang et al. 2021, PNAS
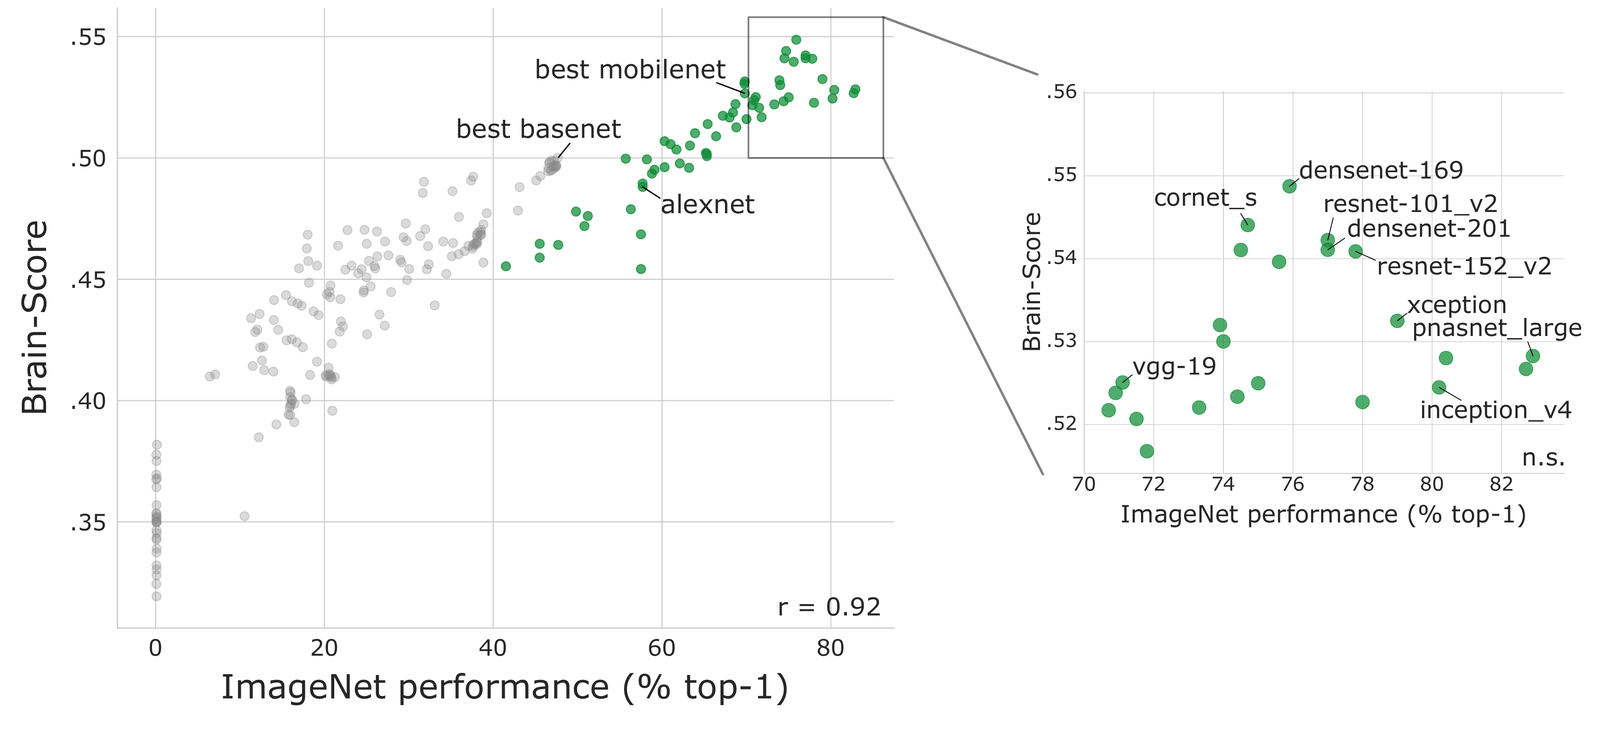
Brain-Score against ImageNet top-1 accuracy across many networks: correlated overall (r = 0.92) The networks above 70% top-1, zoomed in: no significant relationship
Schrimpf et al. 2018, bioRxiv

DINOv3

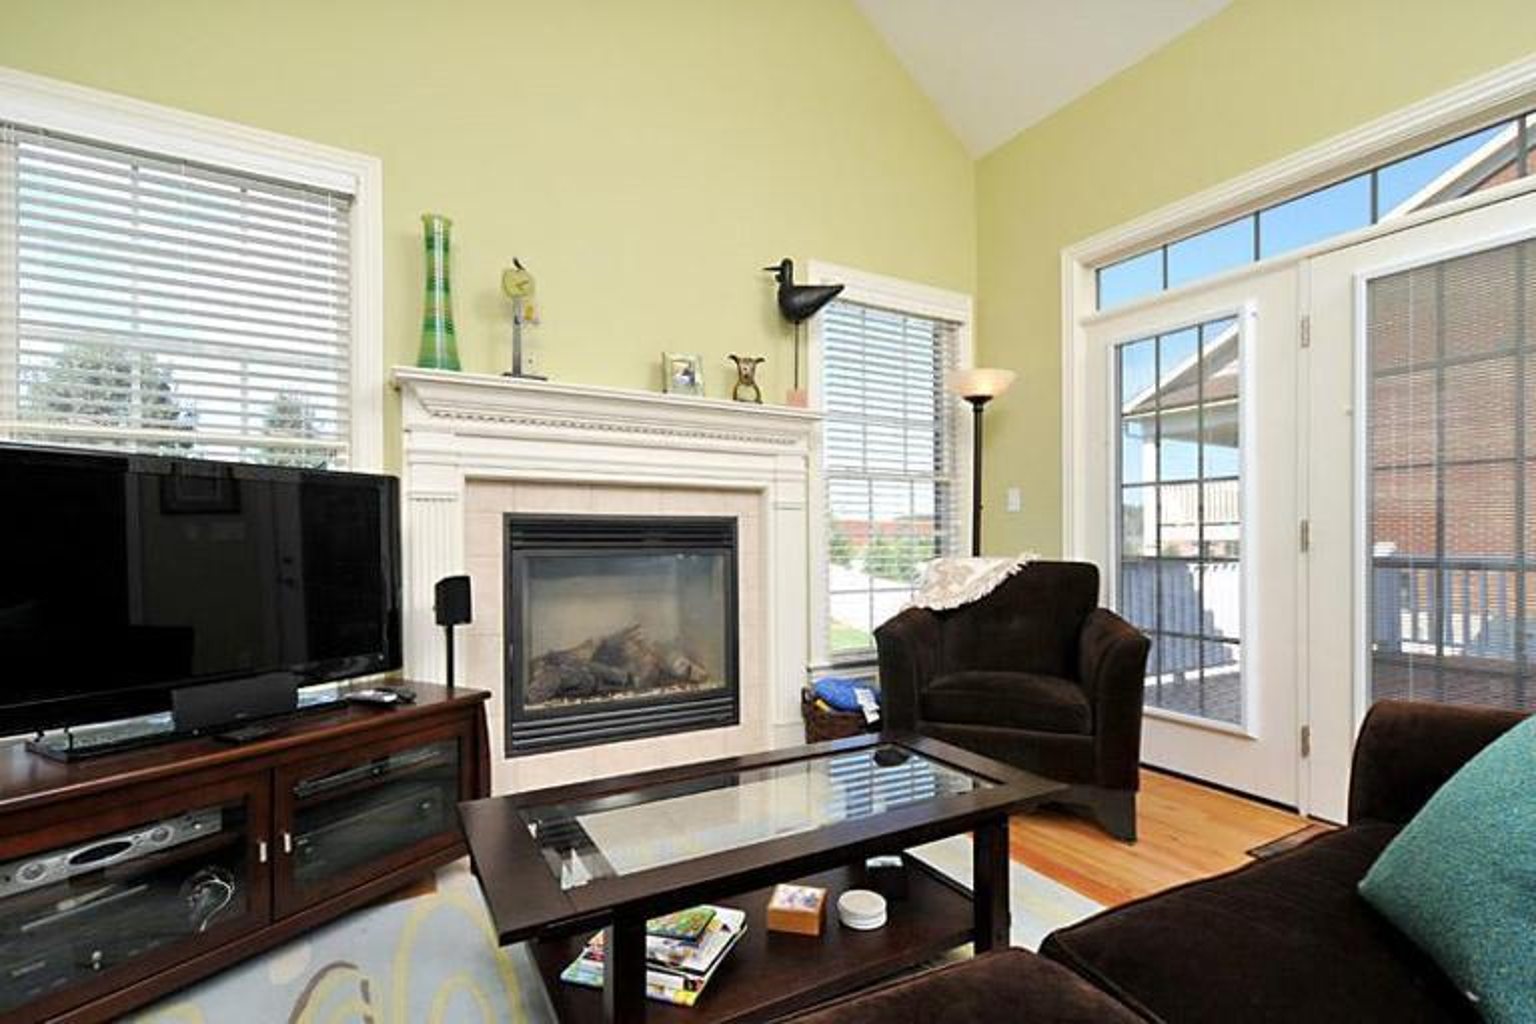
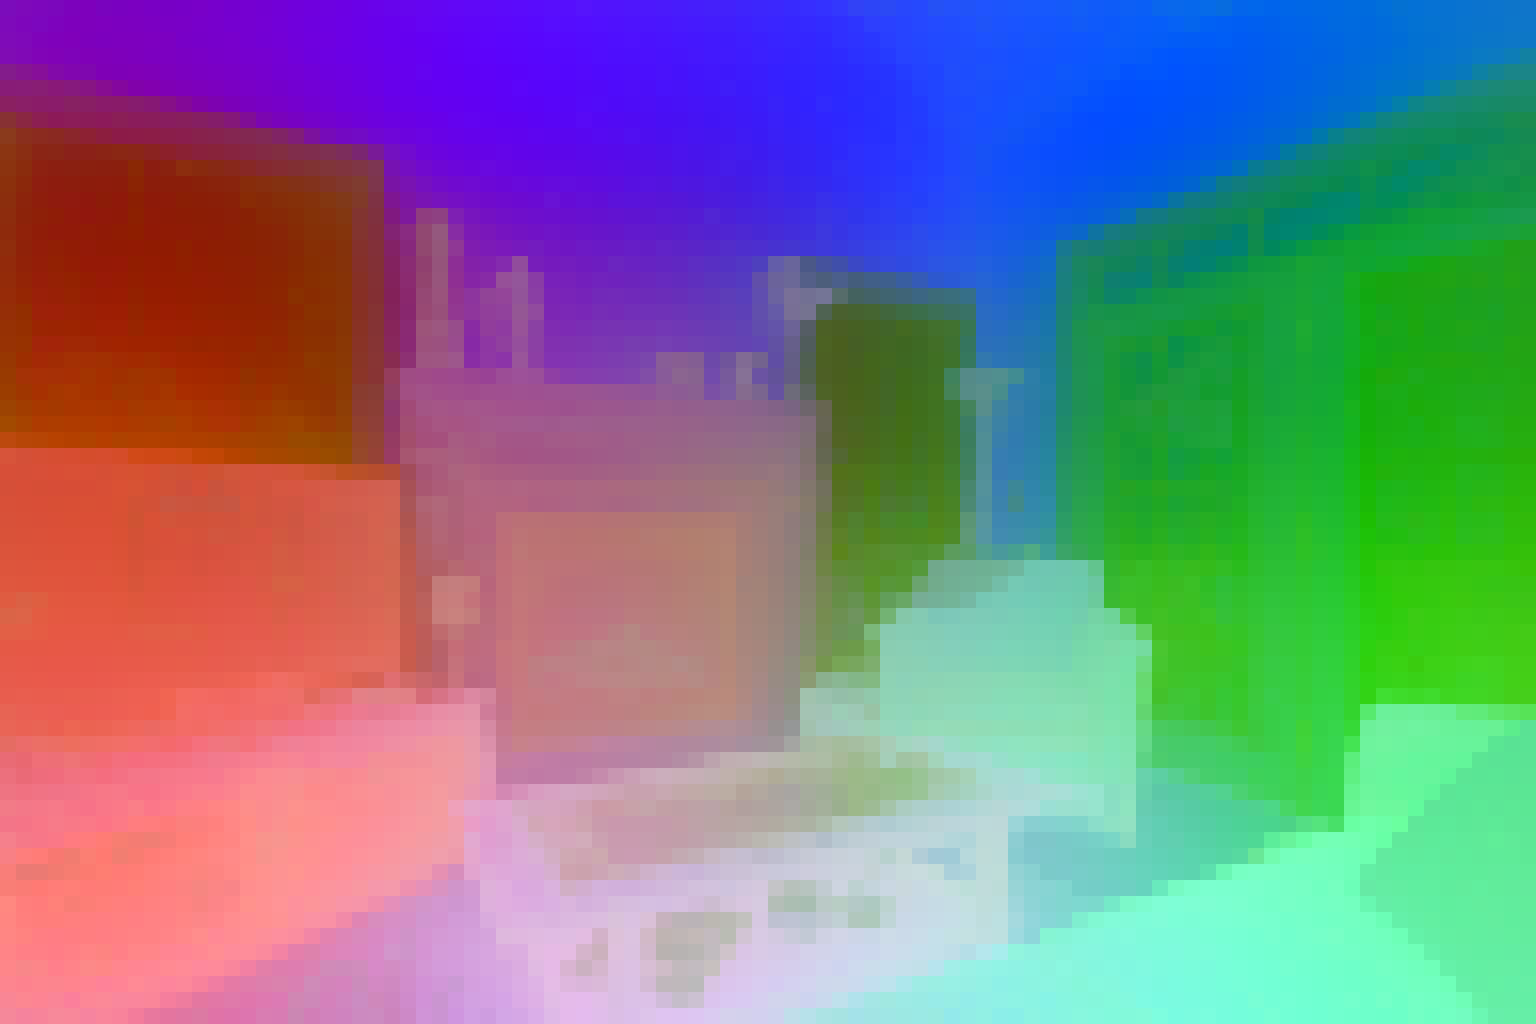
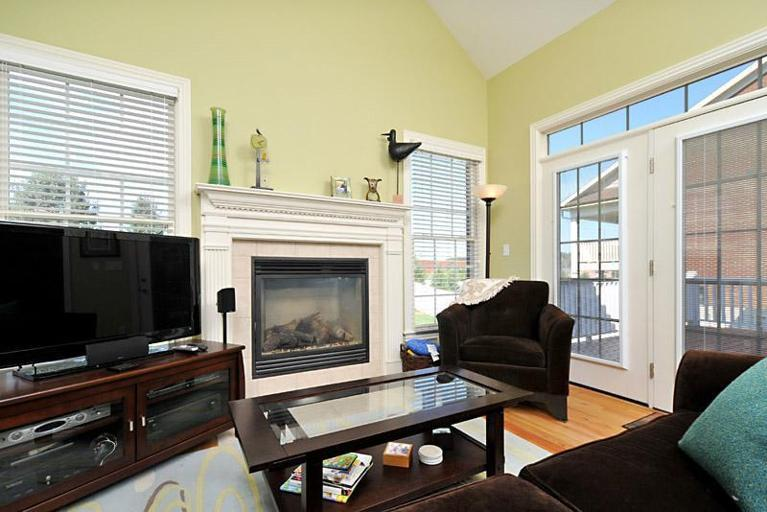
A living room DINOv3's patch features as colors: television, fireplace, windows, armchair and floor each in their own color

linear decoding
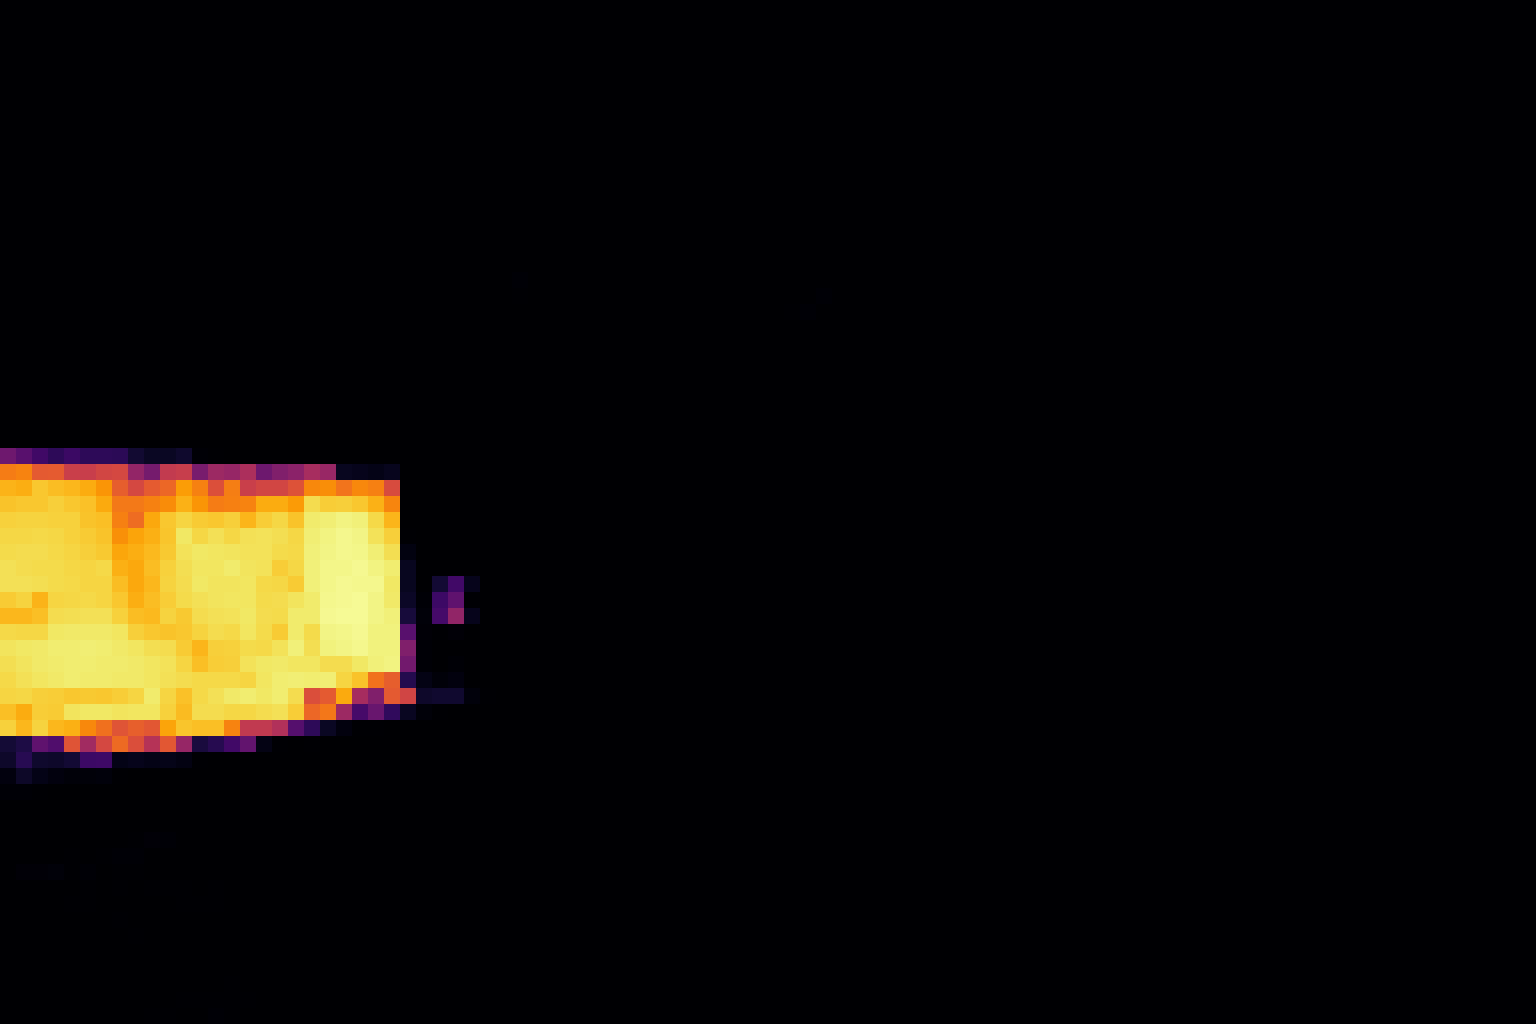
television
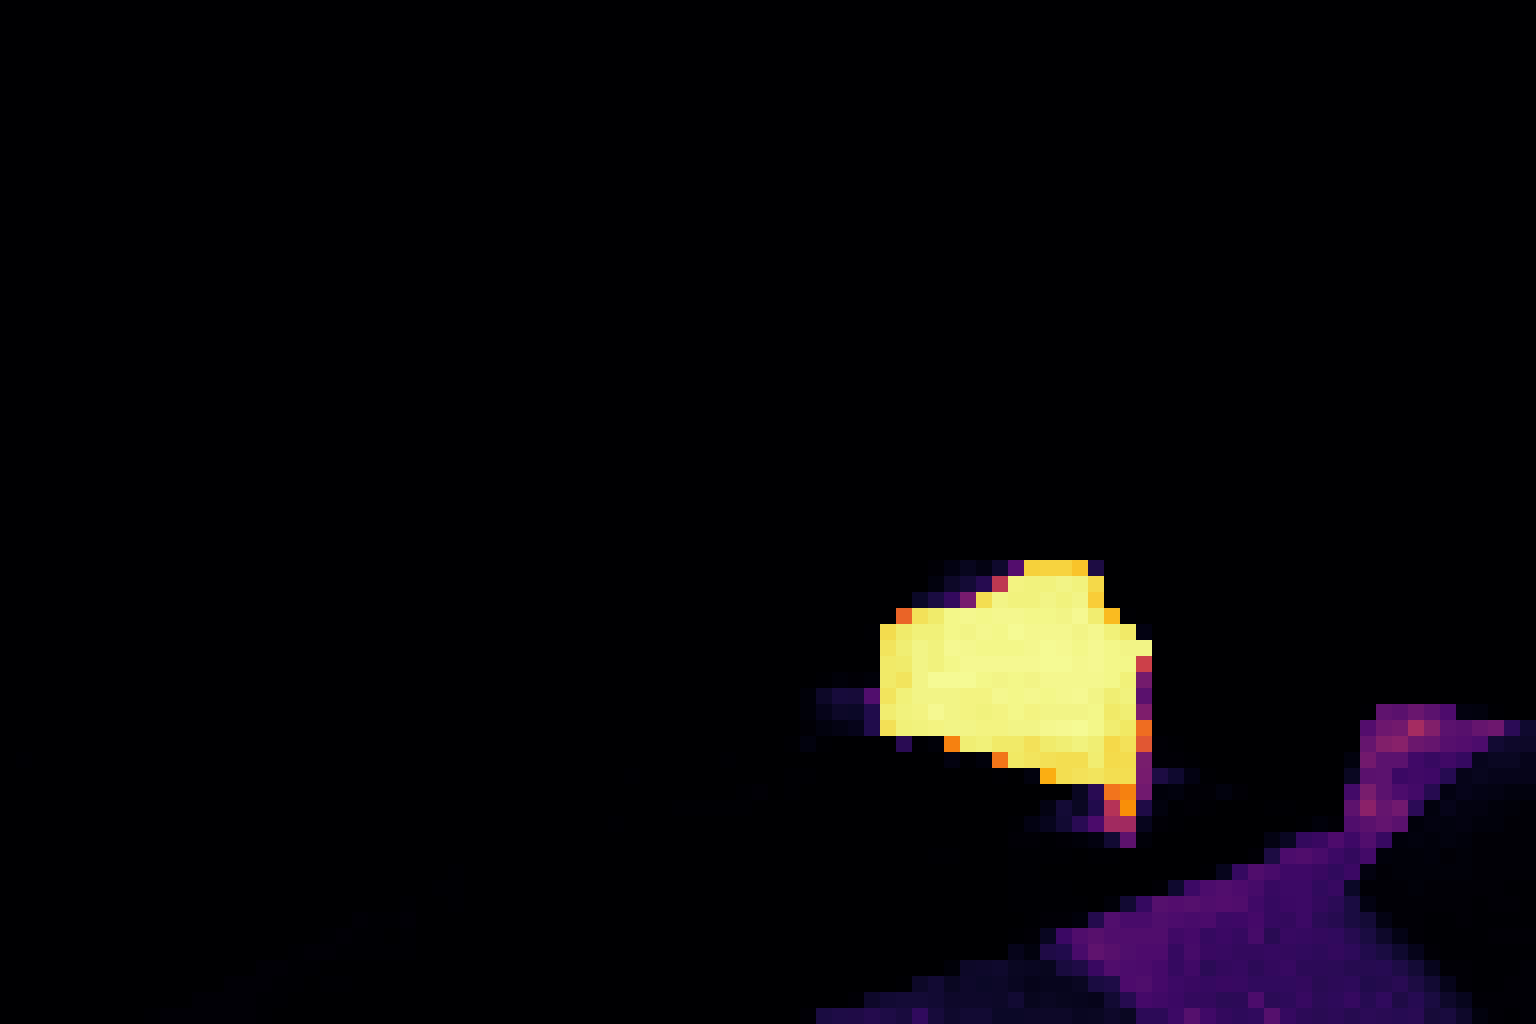
The probability of television: bright on the TV only
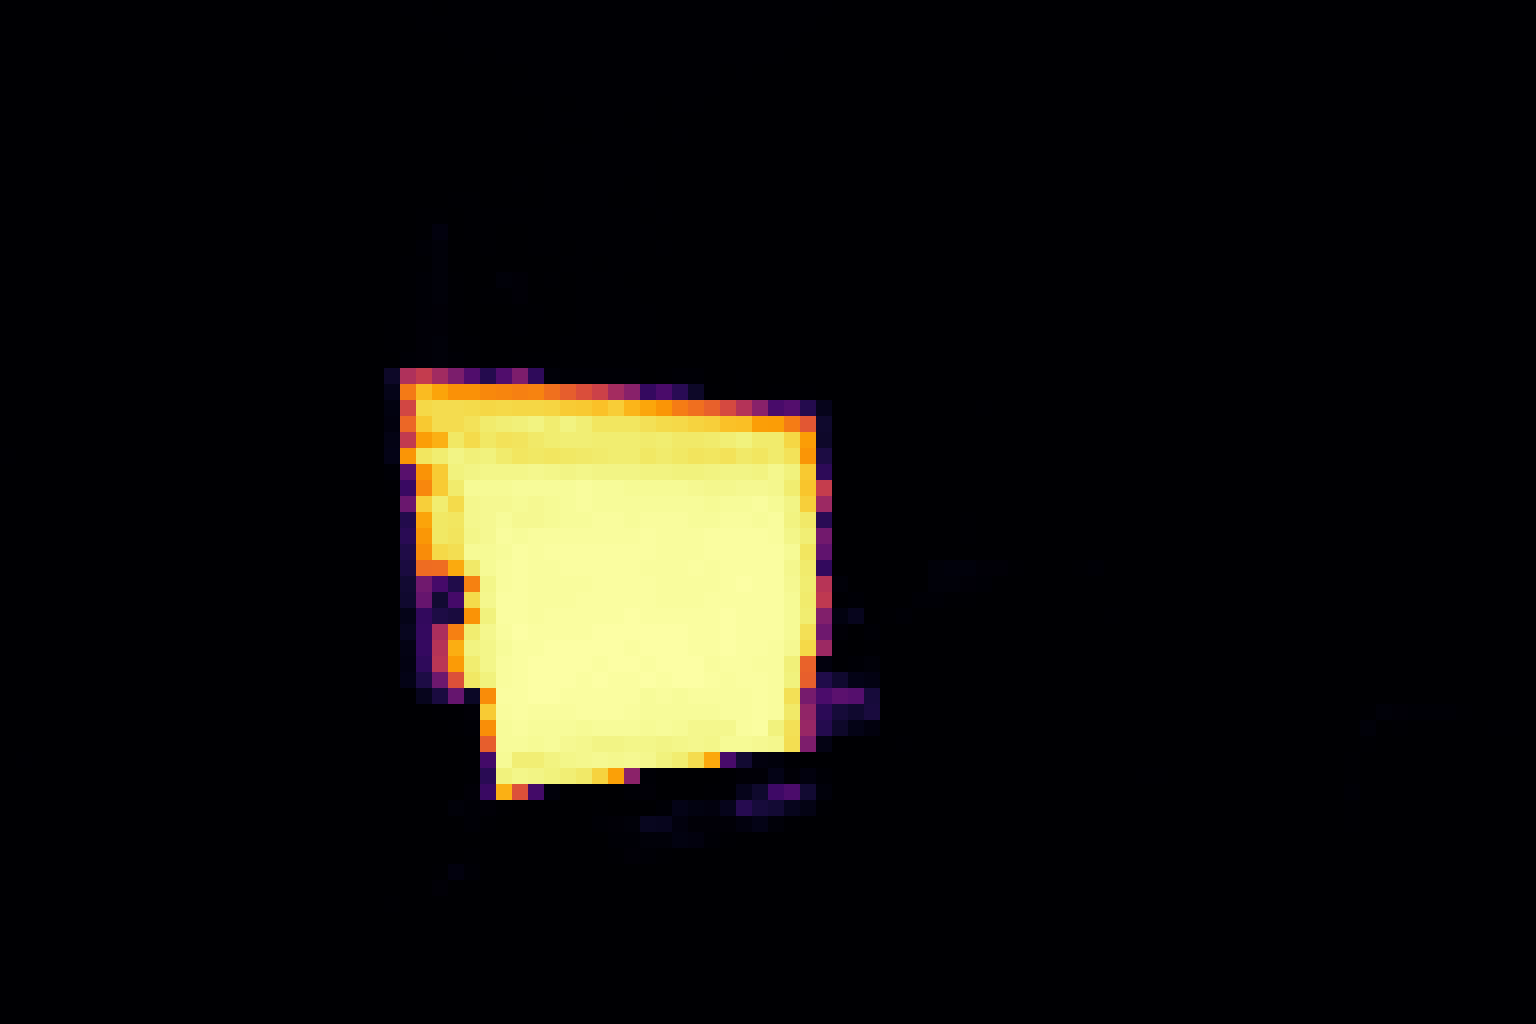
fireplace
The probability of fireplace: bright on the fireplace only
armchair
The probability of armchair: bright on the armchair only
The living room with boxes around the chair, the TV, the vase and the couch
object detection
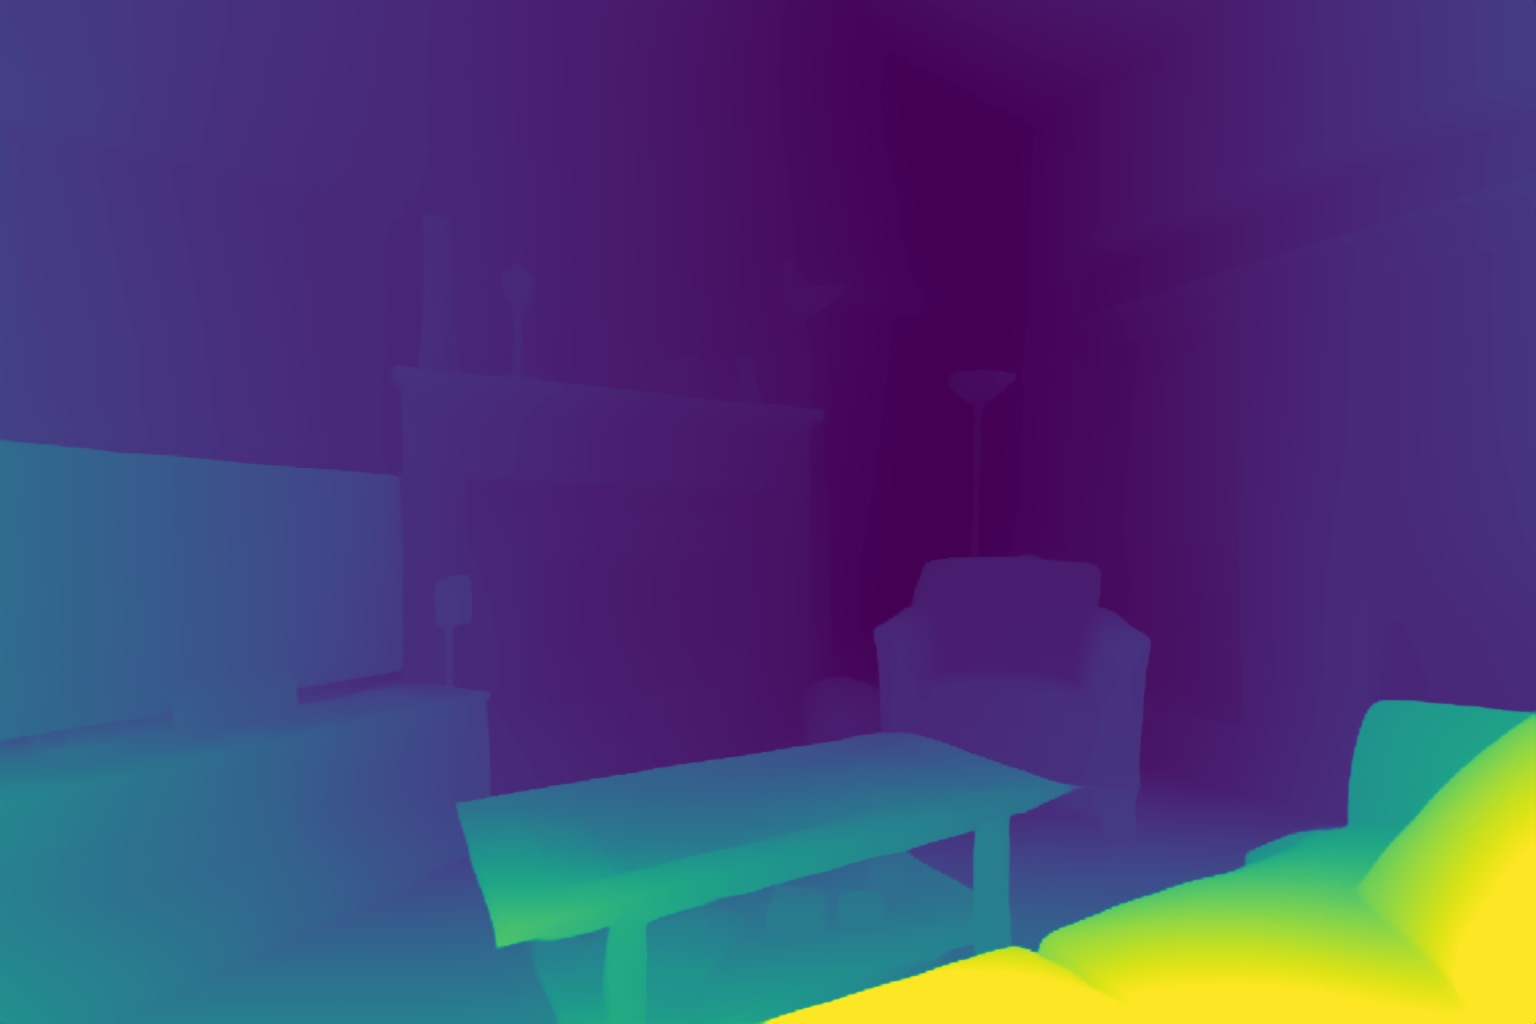
Depth: the couch and table near and bright, the far corner dark
depth

Siméoni et al. 2026, TMLR (DINOv3 ViT-B/16)

Siméoni et al. 2026, TMLR (DINOv3)

DINOv3 and the brain

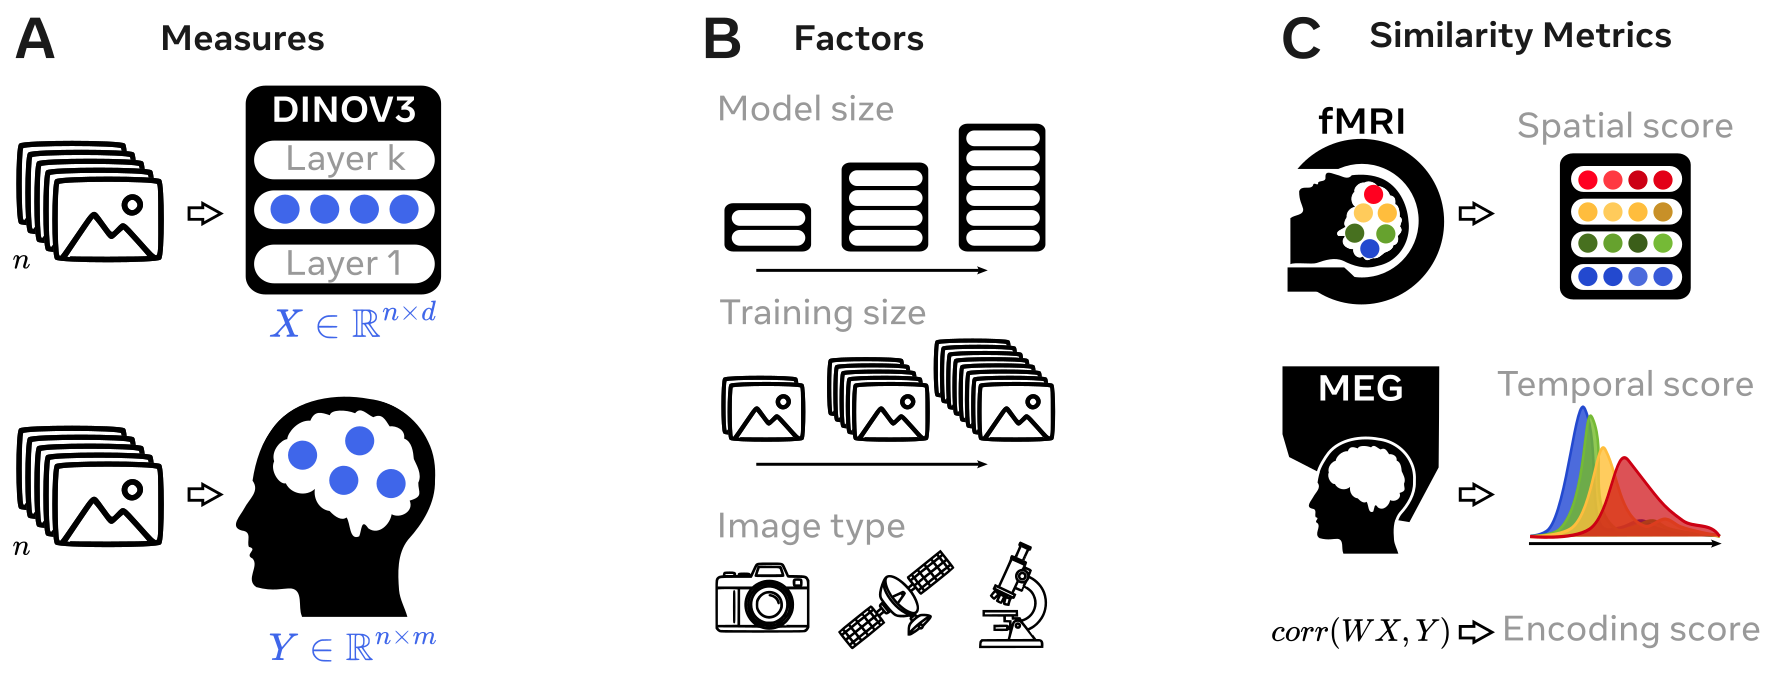
The paper's OpenReview page: Disentangling the Factors of Convergence between Brains and DINOv3, Raugel et al., ICLR 2026 PosterThe study's design: images go through DINOv3 and through human brains; DINOv3 models varying in size, amount of training and image type; fMRI and MEG compared with the model by encoding, spatial and temporal scores
Raugel et al. 2026, ICLR (Method Figure)

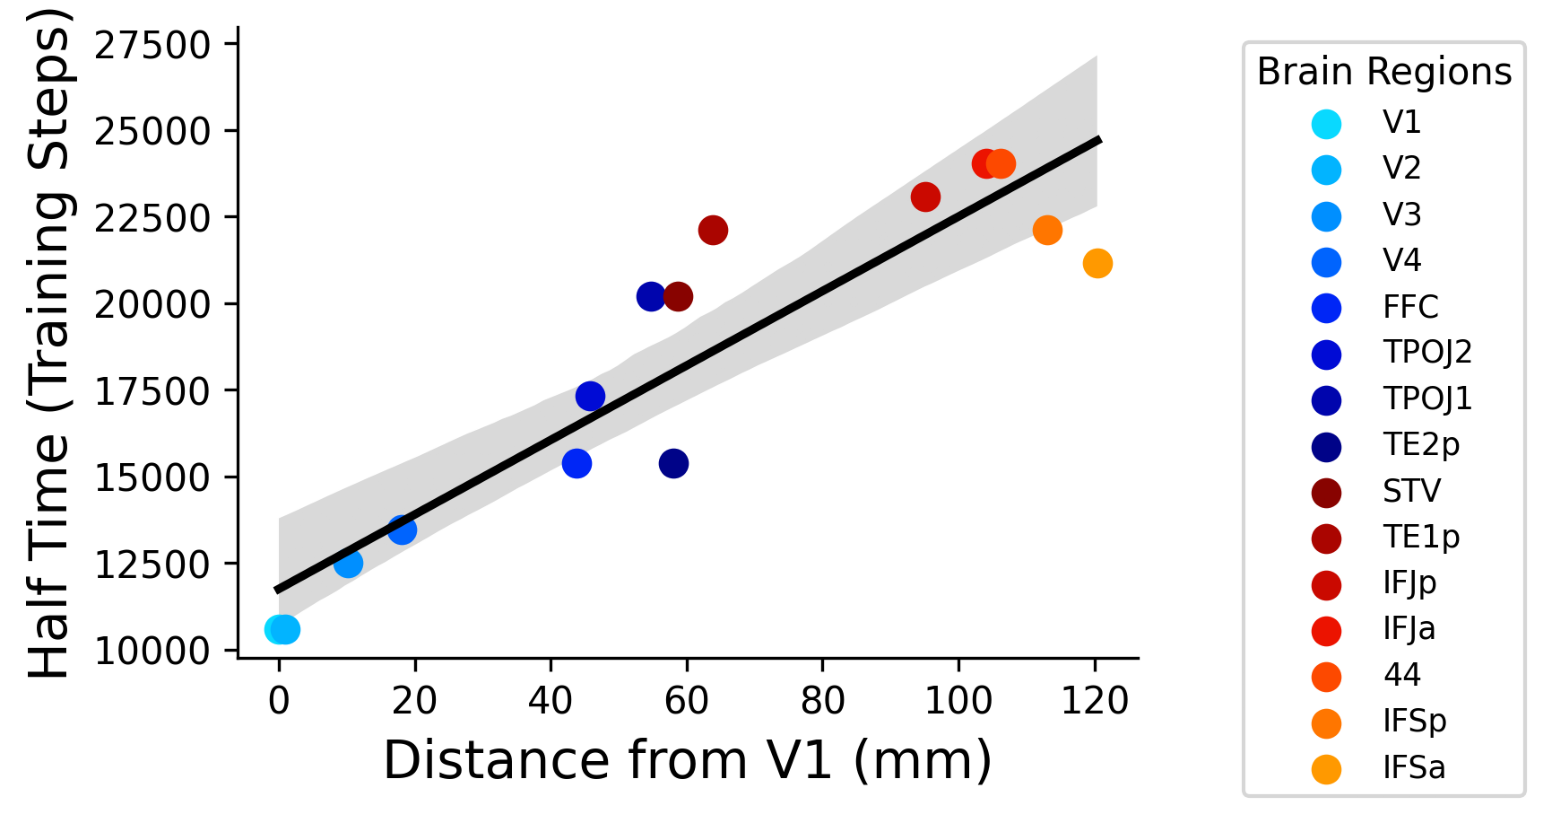
Late alignment with higher-order cortical areas

For 15 cortical regions, the training steps DINOv3 needs to reach half its final encoding score, against the region's distance from V1: early visual areas are matched first, frontal areas only after about twice as much training
Raugel et al. 2026, ICLR (Fig. 4E)

What's missing?

The world Sensory bandwidthComputational resources

Deep active computer vision

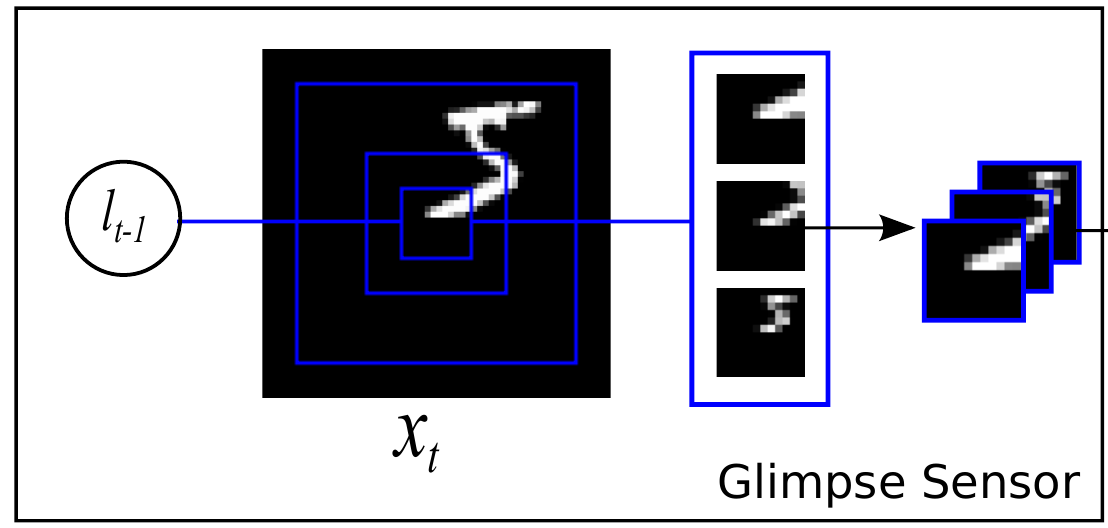
RAM's glimpse sensor: patches of increasing size around a location on an MNIST digit, each resampled to the same resolution
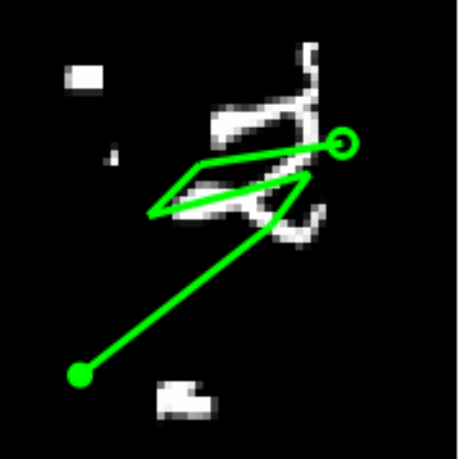
A cluttered digit with the path of RAM's glimpses in green, chosen by its learned policy: from a corner straight to the digit, then around it
Fixation trajectory

Mnih et al. 2014, NeurIPS

The wide gap between passive and active computer vision

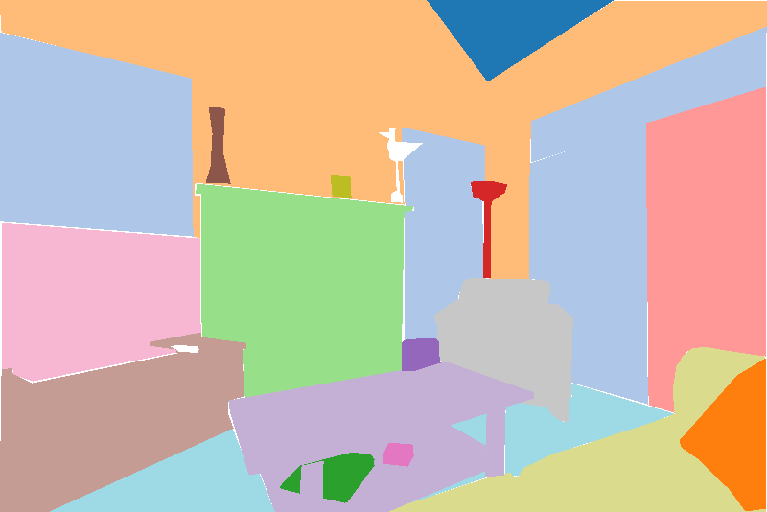
A living roomThe living room's annotation: a class for every pixel
ADE20K semantic segmentationpixel-level

End-to-endFrozen

What's in an active-vision model?

Seeing

Instantaneous vision

Memory

Observer

Choosing where to look

Action selection

Policy

No policy can make up for a poor observer. A general-purpose observer lets you use any policy.

Where people look depends on their goal

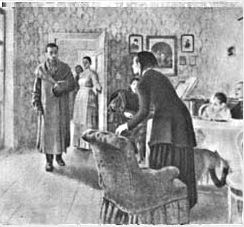
The painting: a man walks into a room where a family sits
Repin, An Unexpected VisitorYarbus 1967, Eye Movements and Vision, Fig. 109
Eye movements under free examination: spread over the whole picture
Free examination
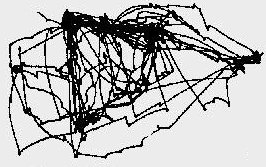
Eye movements while estimating the family’s material circumstances
Estimate the family’s material circumstances
Eye movements while giving the ages of the people: on the faces
Give the ages of the people
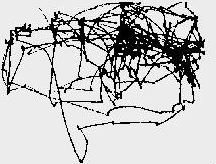
Eye movements while surmising what the family had been doing
Surmise what the family had been doing
Eye movements while remembering the clothes: down the bodies
Remember the clothes worn by the people
Eye movements while remembering positions of people and objects: everywhere
Remember the positions of people and objects
Eye movements while estimating how long the visitor had been away: between his face and the family’s
Estimate how long the visitor had been away

Toward Active-Vision Foundation Models
Passive-Vision
Foundation Models
Prior Active
Vision Models
Active-Vision
Foundation Models
Instantaneous vision✓✓✓
Memory✗✓✓
Visuospatial intelligence✓✗✓
Task-agnostic✓✗✓
Policy-agnostic—✗✓

Canvas Vision Transformer

CanViT

Toward Active-Vision Foundation Models
Yohaï-Eliel Berreby
Sabrina Du
Audrey Durand
B. Suresh Krishna
McGill University Mila – Quebec AI Institute Université Laval
NeurIPS 2026
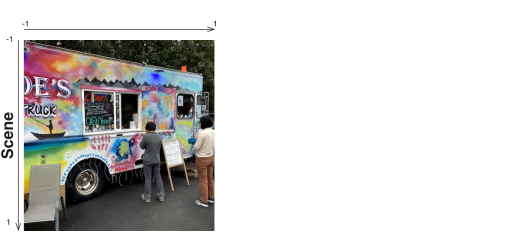
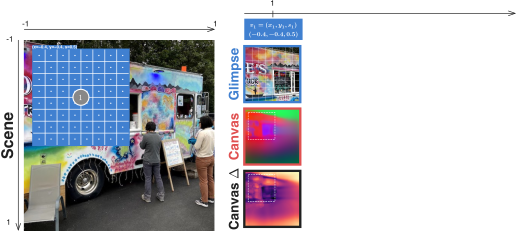
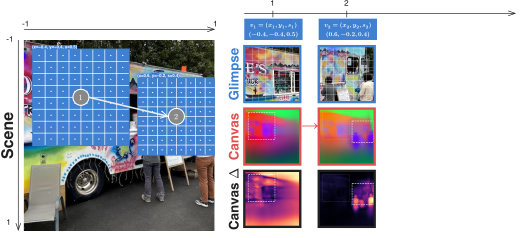
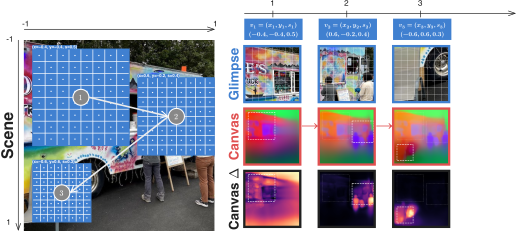
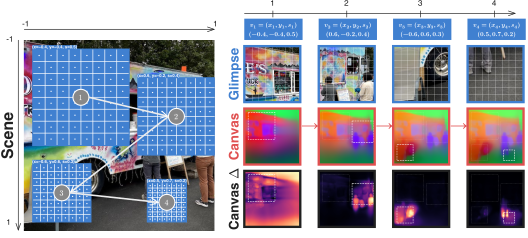
A scene: a food truck The first viewpoint on the scene, its glimpse, the canvas after it, and how much it changed the canvas The second viewpoint and its column The third viewpoint and its column The fourth viewpoint and its column

Architecture

Pretraining

Experiments

Processing a glimpse with a Vision Transformer (ViT)

Scene
Glimpse
Vision
Transformer
The glimpse's patch tokens as colors
Patch tokens

Integrating visual information across viewpoints?
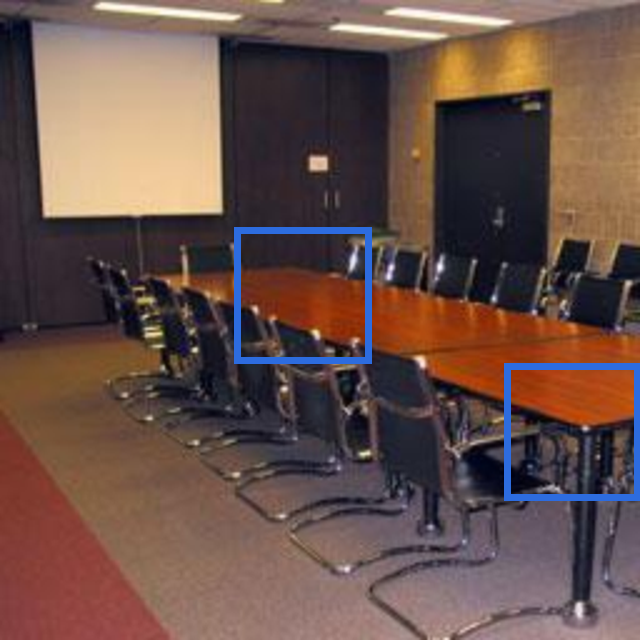
A conference room with a long table The same room, with two glimpses at two corners of the table
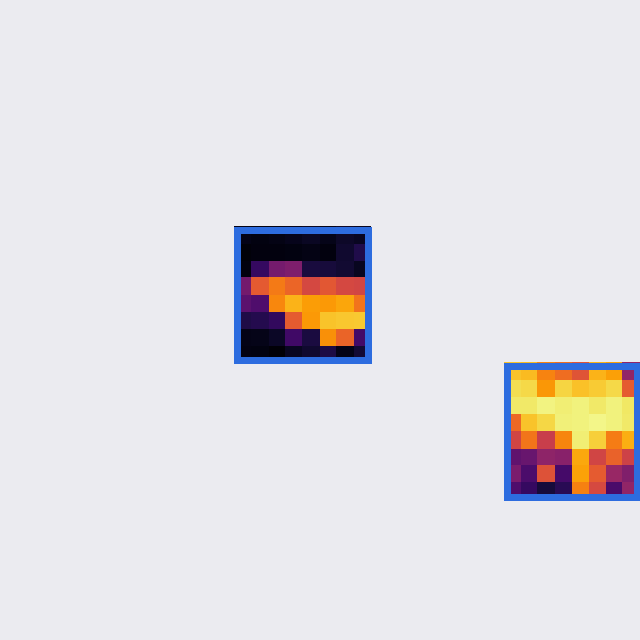
A passive model's probability of table from the far glimpse alone, pasted where the glimpse was taken A passive model's probability of table from the near glimpse alone, pasted where the glimpse was taken ?

01p(table)

The Canvas Vision Transformer
architecture
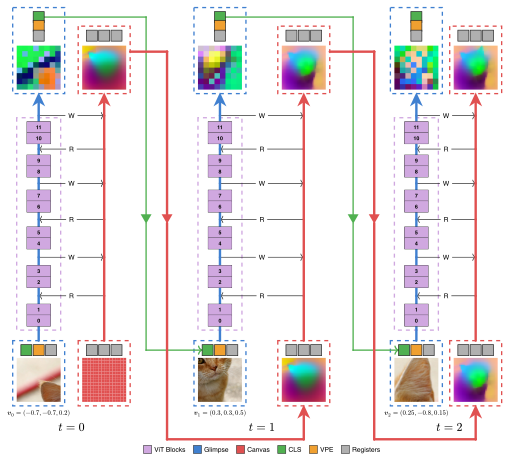
CanViT's architecture over three glimpses: for each, a ViT backbone (purple blocks) processes the glimpse (blue) beside the canvas (red), reading from it and writing to it between blocks; the canvas and a recurrent CLS token (green) carry over to the next glimpse.

Scene-Relative Rotary Position Embeddings (SR-RoPE)

Glimpse
A ginger cat
Scene

Glimpse patchesCanvas patches

Canvas Attention

Architecture

Pretraining

Experiments

Before knowing where to look,
we should know how to see.

Seeing

Instantaneous vision

Memory

Observer

Choosing where to look

Action selection

Policy

Pretraining policies

Policy-agnostic dense latent distillation

Glimpse
(x, y, s)

Prediction

MSE

TargetDINOv3 ViT-B

…

Glimpse 1
CanViT

Glimpse 2

CanViT

Glimpse 3

CanViT

Glimpse 21

CanViT

Pretraining CanViT-B

13.2 millionImageNet-21k scenes

1 billionglimpses

1GPU

CanViT-B

166 H100-hours

DINOv3 7B

61,440 H100-hours
050100150200 020K40K60K

H100-hours

Integrating visual information across viewpoints
A conference room with a long table The same room, with two glimpses at two corners of the table
A passive model's probability of table from the far glimpse alone A passive model's probability of table from the near glimpse alone CanViT's probability of table after both glimpses: the table continues through the middle ?

01p(table)

Architecture

Pretraining

Experiments

Seeing

Instantaneous vision

Memory

Observer

Choosing where to look

Action selection

Policy

Coarse-to-Fine (C2F) and Fine-to-Coarse (F2C)

Entropy-Guided Coarse-to-Fine (EG-C2F)

Accuracy by viewing policy

ImageNet-1k classification
ADE20K segmentation

ADE20K accuracy against inference compute

A new active-vision state of the art

End-to-endFrozen

Learning where to look

Policy learning

640K glimpses

Pretraining

1B glimpses
0200K400K600K 0250M500M750M1B

Glimpses

Open-source and easy to use

uv add canvit-pytorch

scene.jpg
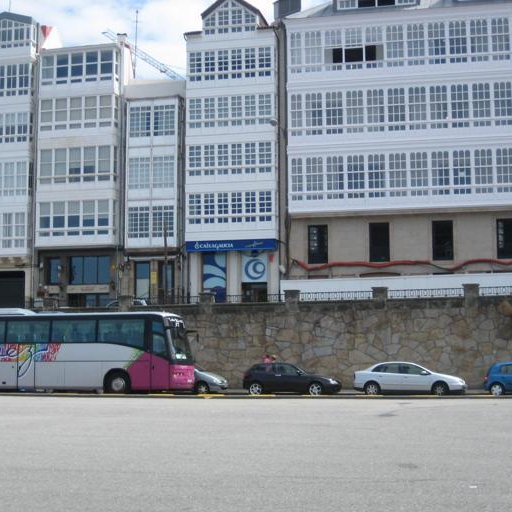
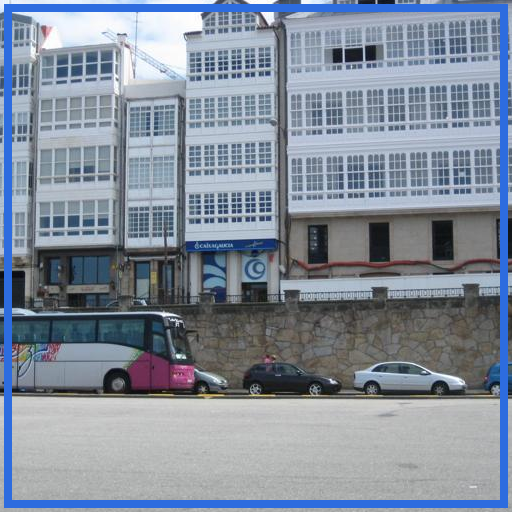
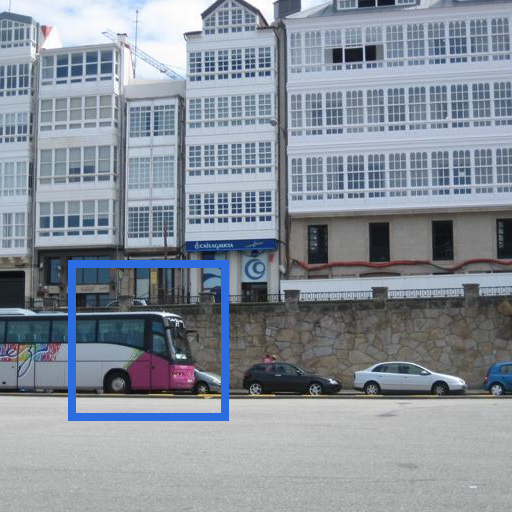
A seafront street with a bus The scene, whole, as the first glimpse The scene, with the second glimpse's box on the bus
logits.argmax(1)
The segmentation after the first glimpse
The segmentation after the second glimpse: the bus, which was car, is now bus

Toward CanViT 2

CanViT

Static scenes (images)

Uniform acuity

Appendix

An emergent hierarchy within each glimpse

The paper's cat, with the glimpse's box
Scene
The glimpse, with its 8 by 8 patches
Glimpse

Canvas Attention Write residuals

What the first write adds: the glimpse's grid of patches
Write 1
What the second write adds: the objects inside the glimpse
Write 2
What the third write adds: the scene beyond the glimpse
Write 3

CanViT in action

Extrapolation to unobserved regions

DINOv3, each glimpse

CanViT, far end

CanViT, near end

CanViT, both

Classes
p(table)
Spatial coverage and perception of detail
Scene
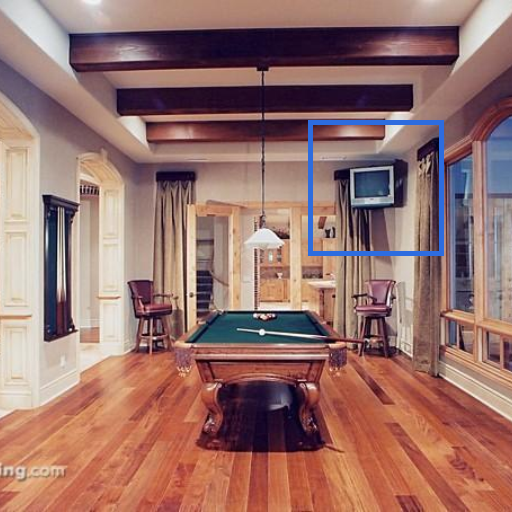
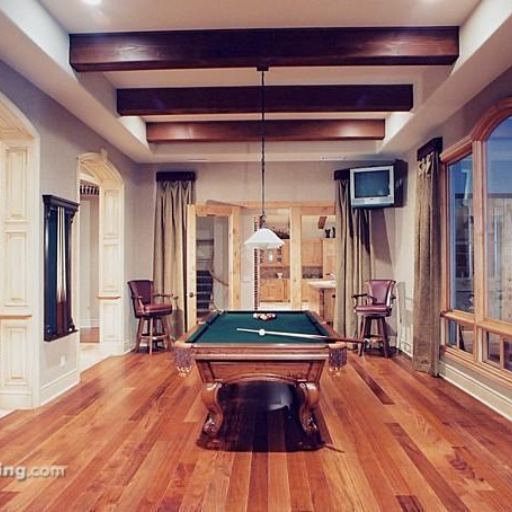
A billiard room with a television on the far wallThe same room with the zoomed glimpse's box around the television
CanViT's input, 128 px
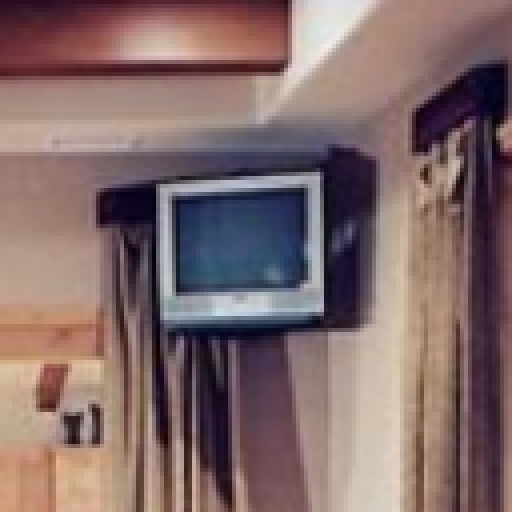
The whole scene in 128 by 128 pixels The zoomed glimpse in 128 by 128 pixels: a television
After the full-scene glimpse: nothingAfter the zoomed glimpse: the television
DINOv3 on the whole scene at 128 px: nothing